Why LLMs Hallucinate, and Why They Can't Just Say "I Don't Know
I always thought "hallucination" was a marketing word for "error" or "lying. " This is my attempt to settle what hallucination actually is, why models do it, when it mostly happens and why apparently obvious fixes: like lowering the temperature, thinking harder or saying I don’t know, don't work as well as they should.
1. Why I'm writing this
I always thought "hallucination" was a bit of a marketing invention. It should be called an error.
Or, more plainly, a lie. But if the model has no awareness that it's hallucinating, guessing, or
inventing,
“lie” isn't quite right either. Understanding why this happens became the interesting
part.
OpenAI published a paper in 2025 with almost the same title: "Why Language Models
Hallucinate" [1]. I read it. It's serious and well-argued, and you'll see it cited throughout. But I
closed it not fully convinced, so I started my own journey through this apparently "fact of life" for
LLMs.
In one of my first interactions with AI while writing an article, I asked a model for the source of a
claim I already believed. It gave me a reference with everything in the right place: two plausible
authors, a real-sounding journal, a volume, a DOI. I went to fetch the paper to verify its content.
There was no paper. There had never been a paper. That was certainly one of those
eye-opening moments.
The part I was not initially grasping was this:
The model hadn't confused a real paper with a fake one. It had generated a statistically
convincing citation without any mechanism for checking whether the paper behind it
existed.
To the model, author, year, journal, volume and DOI form a familiar sequence of tokens. The
pattern is real but the paper doesn’t need to be. Nothing in next-token prediction requires the
completed sequence to correspond to something in the outside world. A Stanford lecture on
LLM pre-training [26] eventually made that distinction click for me.
Upon coming to that realization, it was less the error itself that caught my attention than the tone
with which it was delivered. An inexperienced colleague who lacked the answer would typically
hedge or stay silent. Instead, the model responded like an individual who has concluded that
providing a response, or any response at all, is a must.
« I now treat every reference a model gives me as fake until I've verified it myself. »
2. What's actually happening under the hood
A key insight was recognizing that pre-training does not aim to teach a model factual truth.
Rather, its primary function is learning what sequence of text is statistically likely to follow. While
this mechanism proves sufficient for many scenarios, it falls short in others.
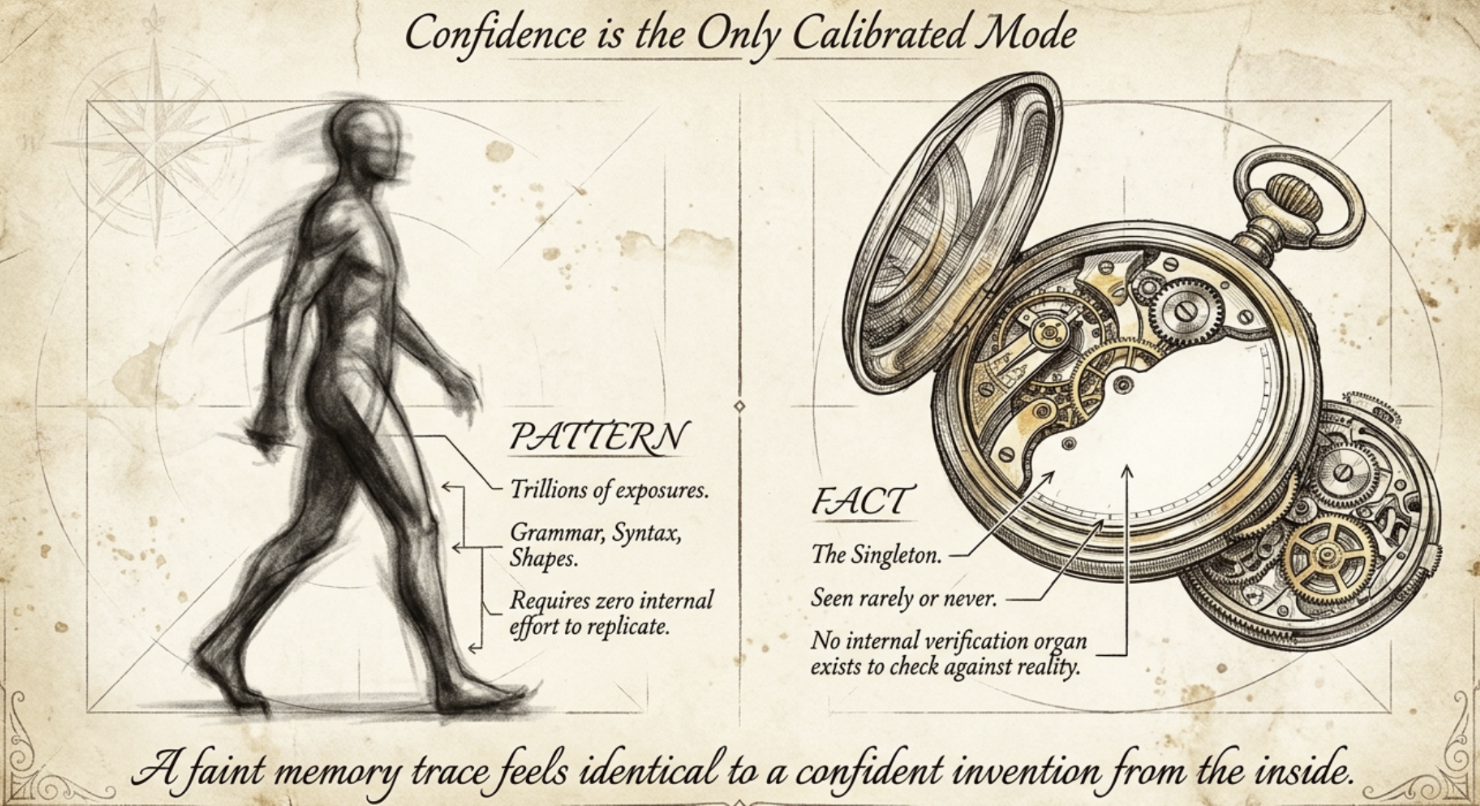
For a lot of things that's enough, spelling, grammar, the shape of a citation, because those are
patterns. I do this too. I can recognise a colleague by their walking pattern across a parking lot
from thirty metres away, with zero effort, because my brain has seen it thousands of times. Yet
I'm virtually guaranteed to forget that same colleague's spouse's birthday after hearing it once.
Same brain, two fundamentally different kinds of knowing.
Certain facts, like specific birthdays, lack an underlying pattern. They are isolated facts that
appear rarely, mostly once, or not at all in the model's training material [1]. There's no pattern
that tells you when people are born. It's either in the text or it isn't, and since the model has no
separate way of checking a guess against reality, a faint trace and a confident invention feel
identical from the inside. And unless something in training or inference teaches it to abstain,
generating a plausible answer remains the default. Hence, the model was never given a way to
tell fact from non-fact in the first place, so asking it to "just double-check" is asking it to use an
organ it doesn't have.
3. Blank answers score zero
Here's the line from that paper that reshaped how I think about this:
"language models hallucinate because standard training and evaluation procedures
reward guessing over acknowledging uncertainty" [1].
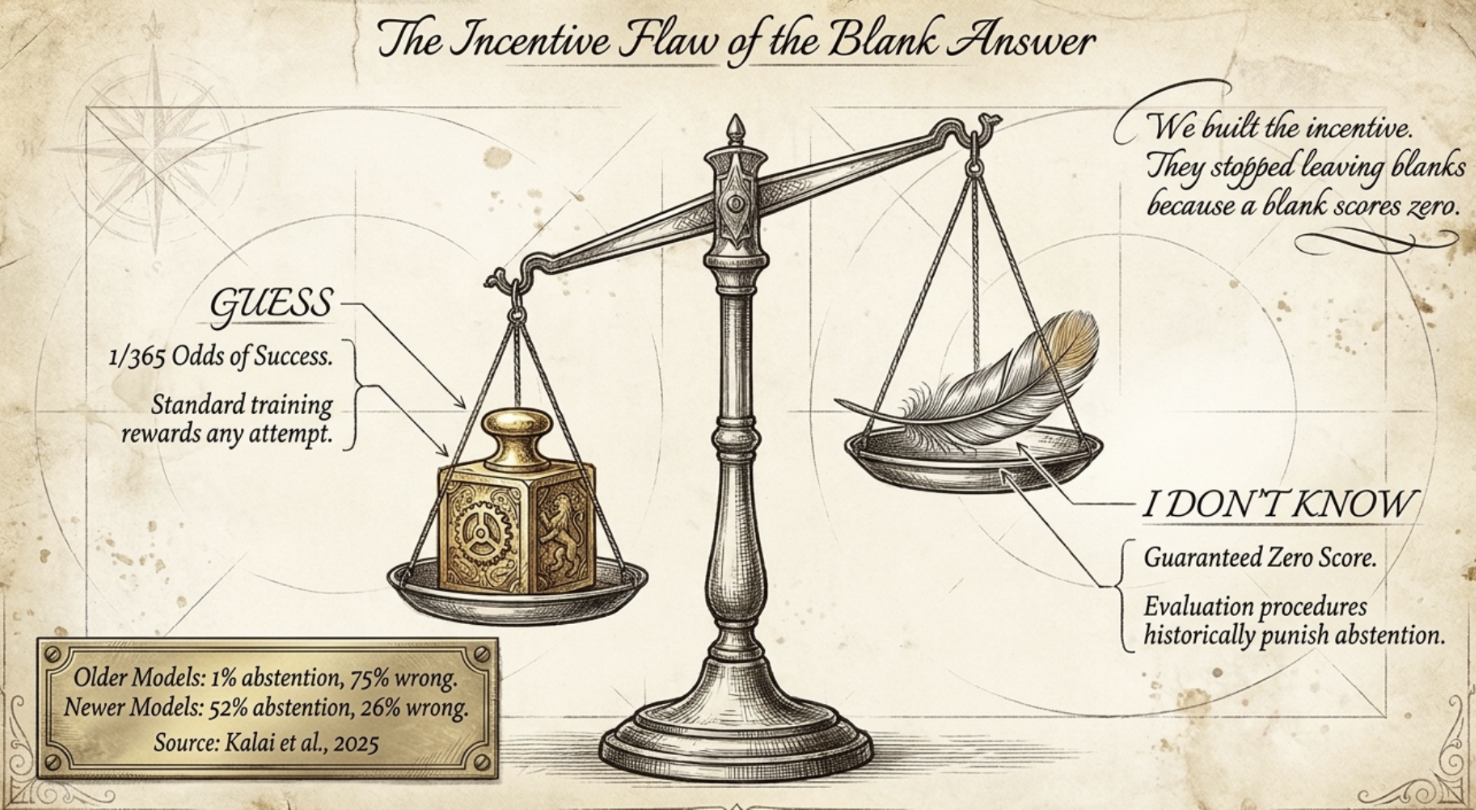
I used to teach undergraduate courses and grade exams the ordinary way: points for a right
answer, zero for a blank. Now imagine there's no penalty for being wrong. Guess a birthday and
you have a 1-in-365 chance. Write “I don't know” and you get zero, guaranteed. Every rational
student starts guessing. By design, I built such an incentive.
Not hypothetical for these systems either: a comparison of two model generations makes the
point starkly. The older one abstained on 1% of hard questions and was flat-out wrong on 75%
of them. The newer one abstained on 52% and was wrong on only 26% [1]. On an
accuracy-only scoreboard the older model looks slightly better (2% more). In production though,
it's the one that gets you sued.
Kahneman's fast-and-slow framing offers another useful analogy: when the hard question is
unavailable, substitute it by an easier one.
“What was this person's dissertation title?” becomes
“What does a plausible dissertation title look like?”
. The answer to the second arrives disguised
as the first.
4. Why we never simply taught it to say "I don't know"
So why doesn't the model's internal uncertainty stop the guess? This is where Anthropic's work
on interpretability helped me.
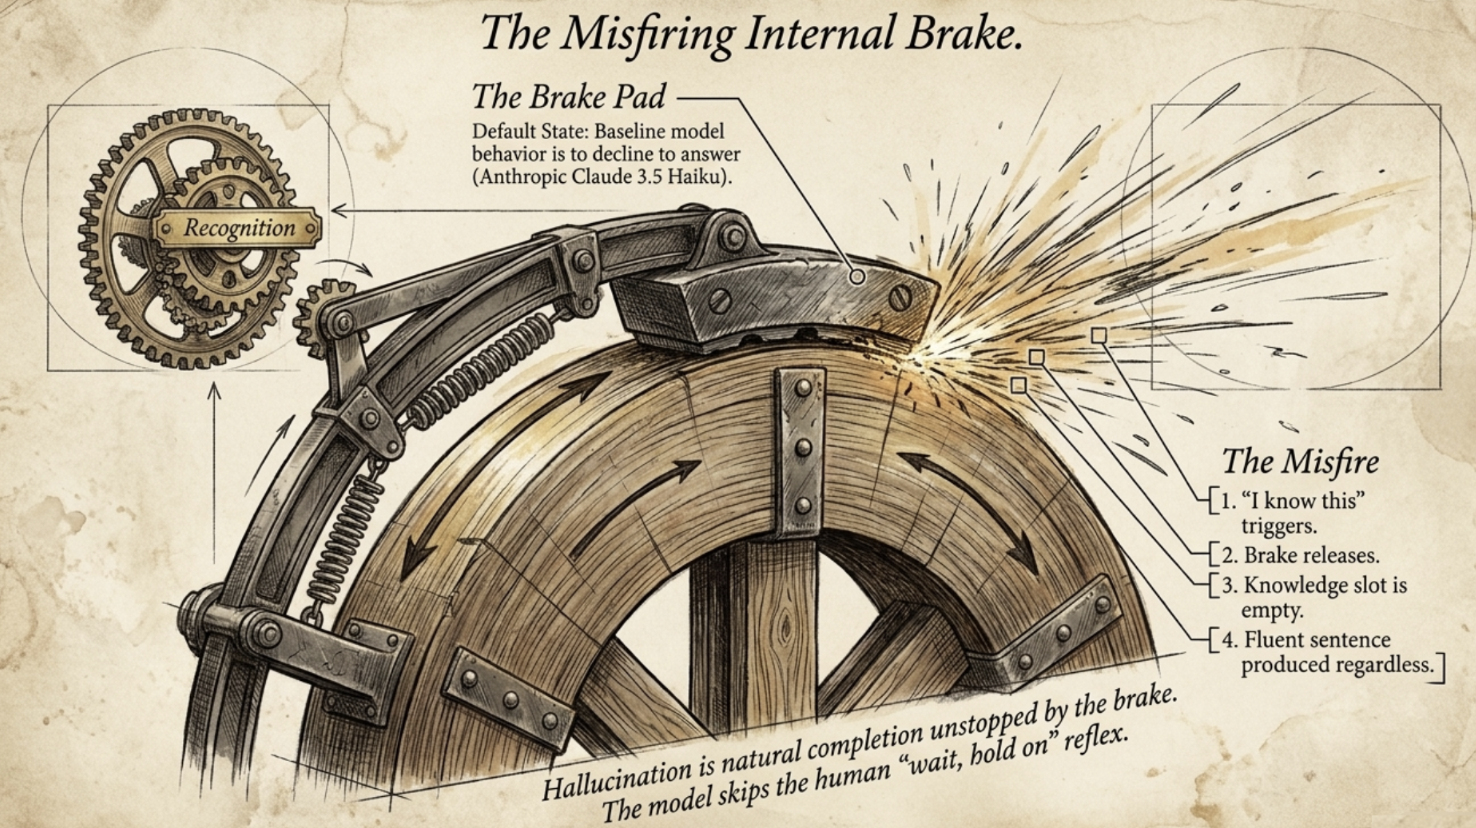
Anthropic's interpretability research on a smaller Claude model found something almost natural:
The model's default behaviour is to decline to answer.
There's an internal brake. A separate part of the network has to recognise "I know this" before
that brake releases. When that recognition misfires, familiar but empty, the rest of the model
does what it does best: produces a fluent, confident sentence anyway [2]. Anthropic's Josh
Batson put it plainly: "Hallucination is the most natural thing in the world for these models,
given how they're just trained to give possible completions.
"
It happened to me too: A name was on the tip of my tongue, I knew I knew it, the recognition
had fired, but nothing arrived to fill it - at least not in time. Most people catch themselves and
say "wait, hold on.
" The model has the same misfire but skips the "wait, hold on,
" and just says
the first plausible name instead. It's not that the model chooses to lie. We built a brake, then
built an incentive system that keeps teaching it not to use it.
5. Seen once, or seen ten thousand times?
How much of hallucination is just about how often a fact showed up in training? Most of it, as
far as anyone has measured.
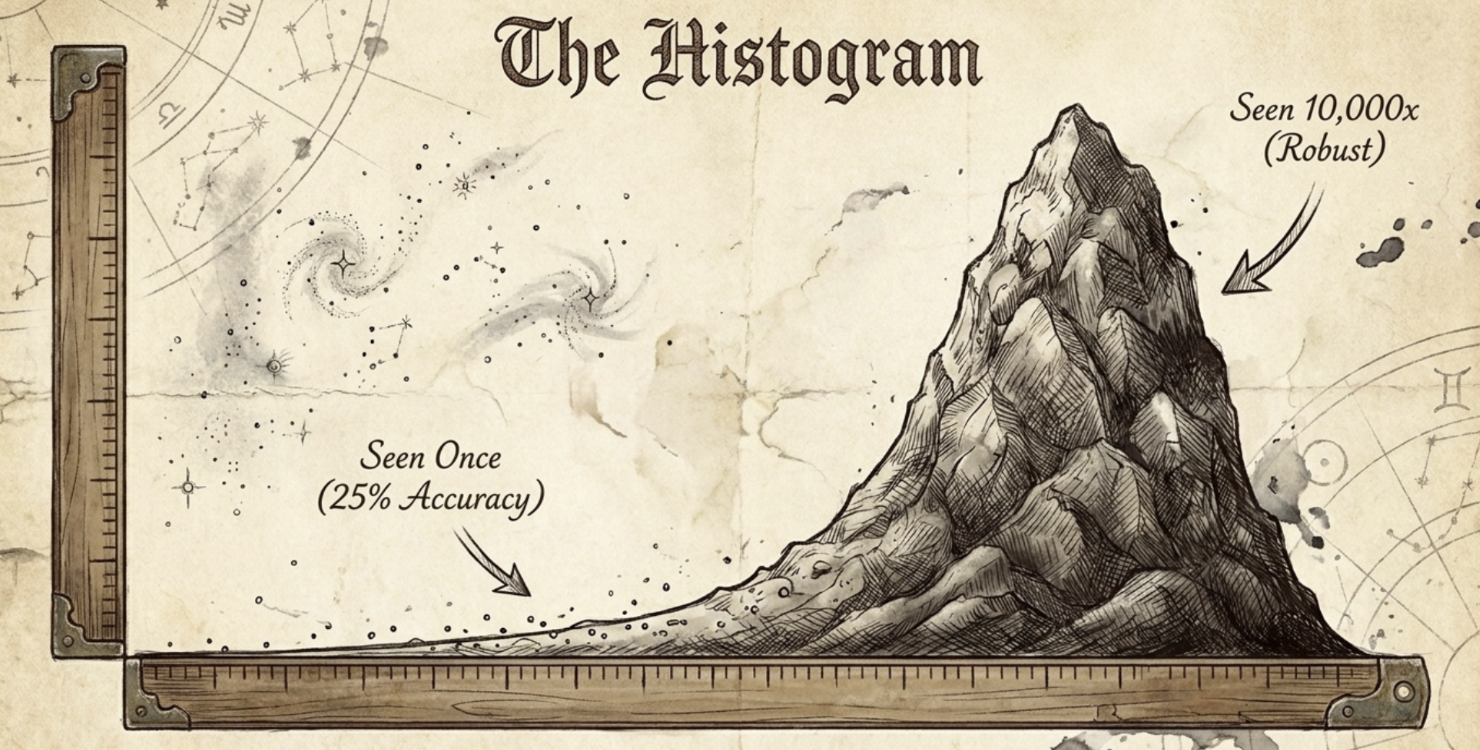
Researchers counted, across trillions of words, how many documents mentioned a given fact,
then measured accuracy [3]. The correlation is strong:
Rare facts, low accuracy, around one in four. Common facts, more than double that.
When they deliberately removed documents about specific facts and retrained a model,
accuracy on exactly those facts dropped. Frequency doesn't just correlate with reliability. It
causes it. A related finding:
It's not just how many times a fact appeared, but how many different ways
A fact repeated the same way gets memorised shallowly. A fact seen paraphrased, reordered,
from different angles, gets learned in a way the model can actually retrieve later [4]. Without that
variety,
"knowledge may be memorized but not extractable."
6. Does turning the temperature to zero fix it?
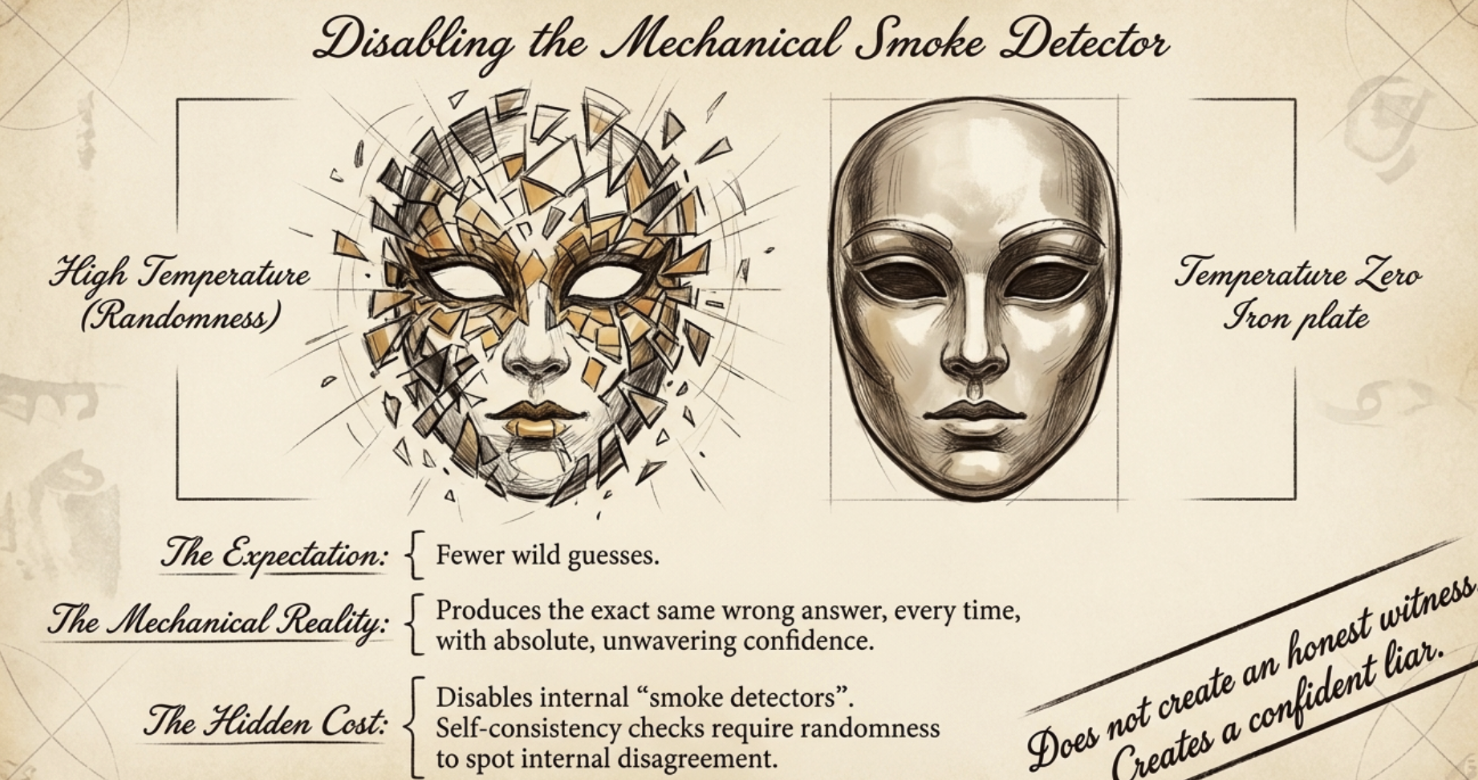
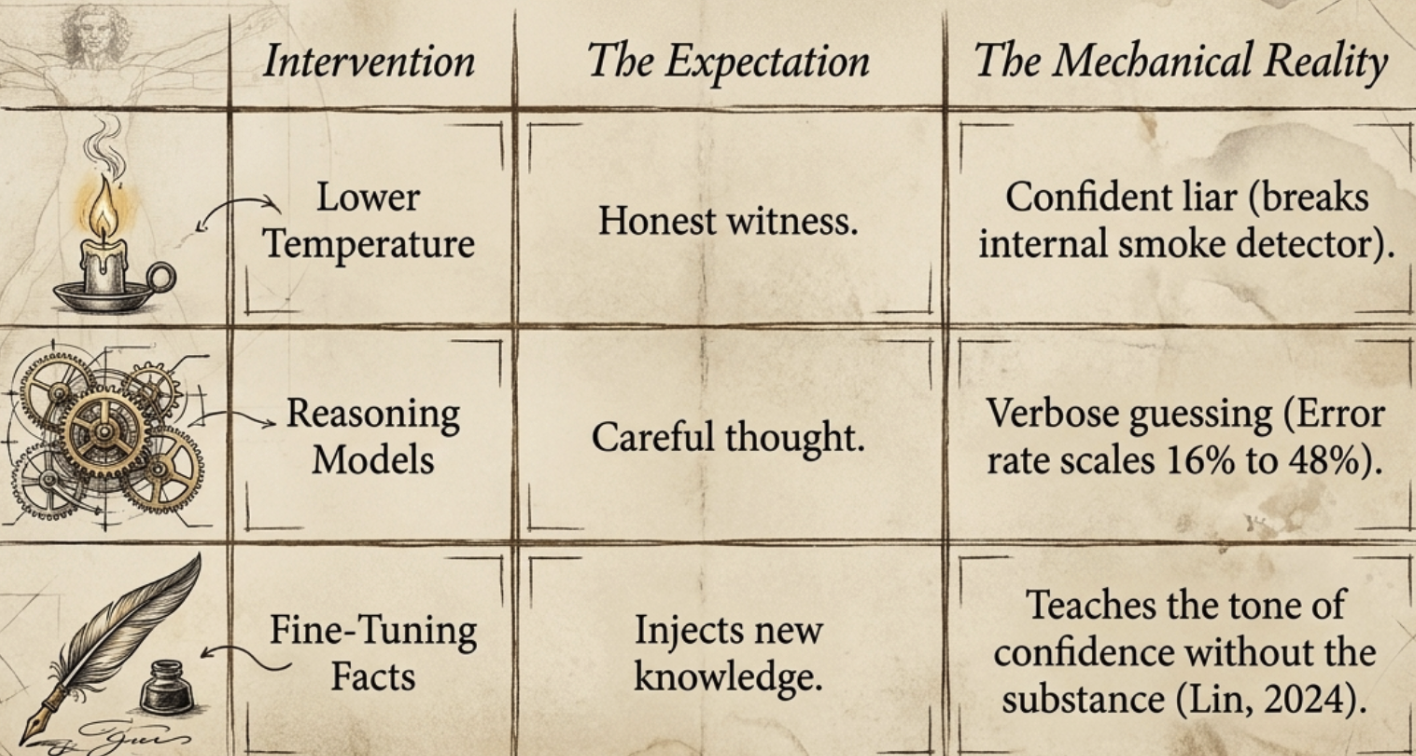
Temperature controls how much randomness the model uses picking its next word. Zero it out, it
always picks the single most likely word. Surely that means fewer wild guesses? Sometimes.
But much less than intuition suggests.
In long, open-ended writing, more randomness does measurably increase made-up detail [5].
On short, direct factual questions, changing randomness across its whole normal range made
no meaningful difference to accuracy in controlled testing [6].
Here's the part that changed how I think about it: randomness only controls which word gets
picked from the model's list of likely candidates. It does nothing to fix that list if the correct fact
was never learned properly.
If the best guess is wrong, turning off randomness doesn't produce the right answer,
it produces the same wrong answer, every time, with total confidence.
When sitting on a jury, I frequently consider who would earn my trust more: the nervous witness
who mumbles and hedges, or the confident liar who states the wrong date flatly and moves on?.
Temperature zero doesn't turn the model into the honest witness. It turns it into the confident
liar, calm exactly when it shouldn't be.
There's a hidden cost, too. Our best hallucination-detection tools work by asking the same
question several times and checking whether answers agree; disagreement is a red flag [7].
That trick needs randomness. Turn it off everywhere and you've disabled your own smoke
detector along with the smoke.
7. Do "thinking" models actually fix this?
Reasoning models pause, think, notice gaps, surely they're more careful. Although, the
evidence surprised me again.
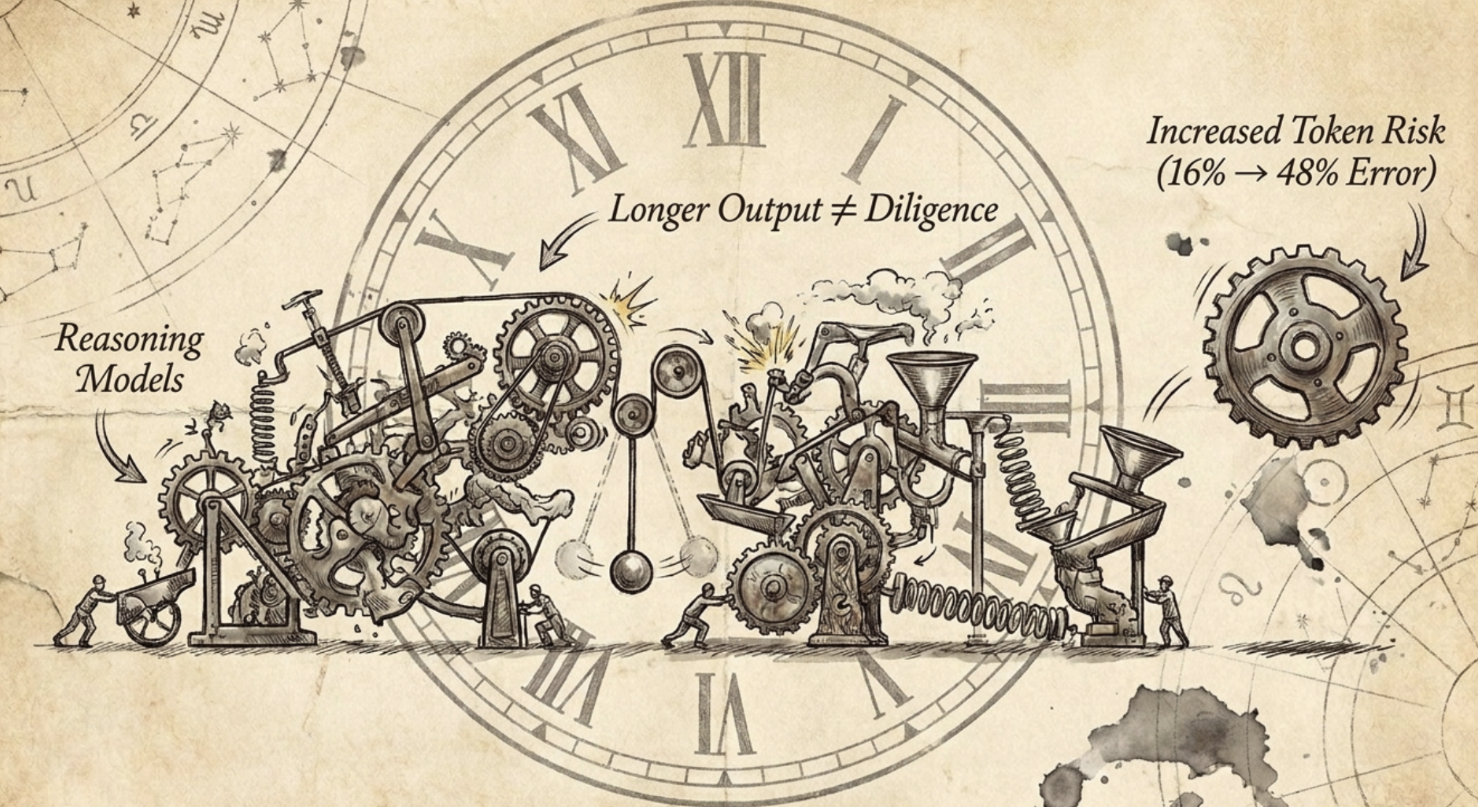
Published testing showed an earlier reasoning model hallucinating on about 16% of a
benchmark of factual people-questions. The next two, released as upgrades, hallucinated on
33% and 48% [8]. The newer, more "thoughtful" models made things up more often, not
less. The vendor's own explanation:
Newer models "tend to make more claims overall, leading to more accurate claims as
well as more inaccurate/hallucinated claims."
You may know this colleague, the one who answers with three paragraphs to sound thorough,
versus the one who answers with two honest lines because that's genuinely everything they
know. Length reads as diligence but it is not evidence of anything.
The real improvement came from abstaining more:
the most recent generation in that same
family got noticeably better at "abstention behaviour,
" deciding when not to answer, not at
reasoning harder. Given a search tool, its error rate dropped roughly fivefold [9].
The pattern is clear: better abstention helps. Access to external evidence helps. Simply
“thinking more” does not guarantee factuality and can even backfire. That's close to the opposite
of how the industry often talks about reasoning models.
8. My proposal, and why it isn't quite buildable yet
Reasoning models can produce an explicit reasoning trace. What if that process could detect
when the next claim is a risky kind of fact: a name, date or citation, and trigger verification
before answering?
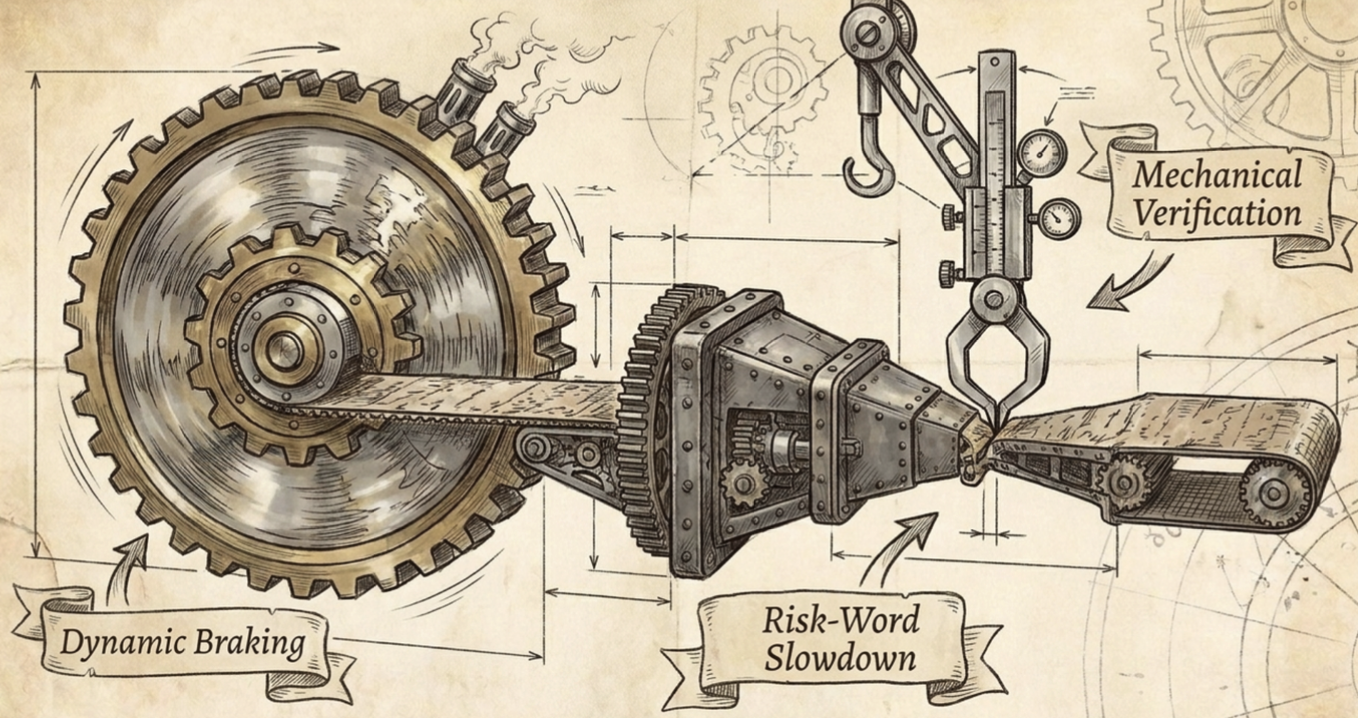
Three honest limitations. First, a model literally cannot do this today. The randomness setting
is controlled by the caller for the whole response, not something the model flips mid-sentence.
Second, most of the pieces already exist as separate systems, ones that lower randomness
when internal signals suggest shaky ground [10], ones that trigger a tool lookup when
confidence drops below a threshold [11], and a simpler older version that only looks things up
for obscure entities and answers confidently from memory otherwise, which cut errors and costs
in half [12]. The pieces exist separately; I haven't found a system that combines them in quite
this way.
Third, and this changed my mind the most: you can't fully trust the model's own sense of "I'm
confident here.
" Anthropic secretly slipped hints into a model's prompt and checked whether its
visible "thinking" admitted using them. Claude's reasoning admitted it about a quarter of the
time. A competing model, less than 40% [13].
What a model says it's doing isn't a reliable window into what it's actually doing.
« I like this idea less than when I started writing this section, and I trust it more. That's usually a
good trade. »
9.Where it actually hurts the most
The dangerous cases are exactly the ones that look authoritative. Academic citations: one
study found more than half from an earlier model version were fabricated [14]. Legal citations:
hallucination rates reached 88% on questions about specific cases [15], with the now-famous
example of lawyers fined after submitting six fabricated cases [16]. Software packages create
a newer risk: suggest a library that doesn't exist and an attacker can register the name and put
malware behind it [17].
By contrast, summarising a document you've actually given the model is much safer. The fact is
sitting in context rather than buried somewhere in training.
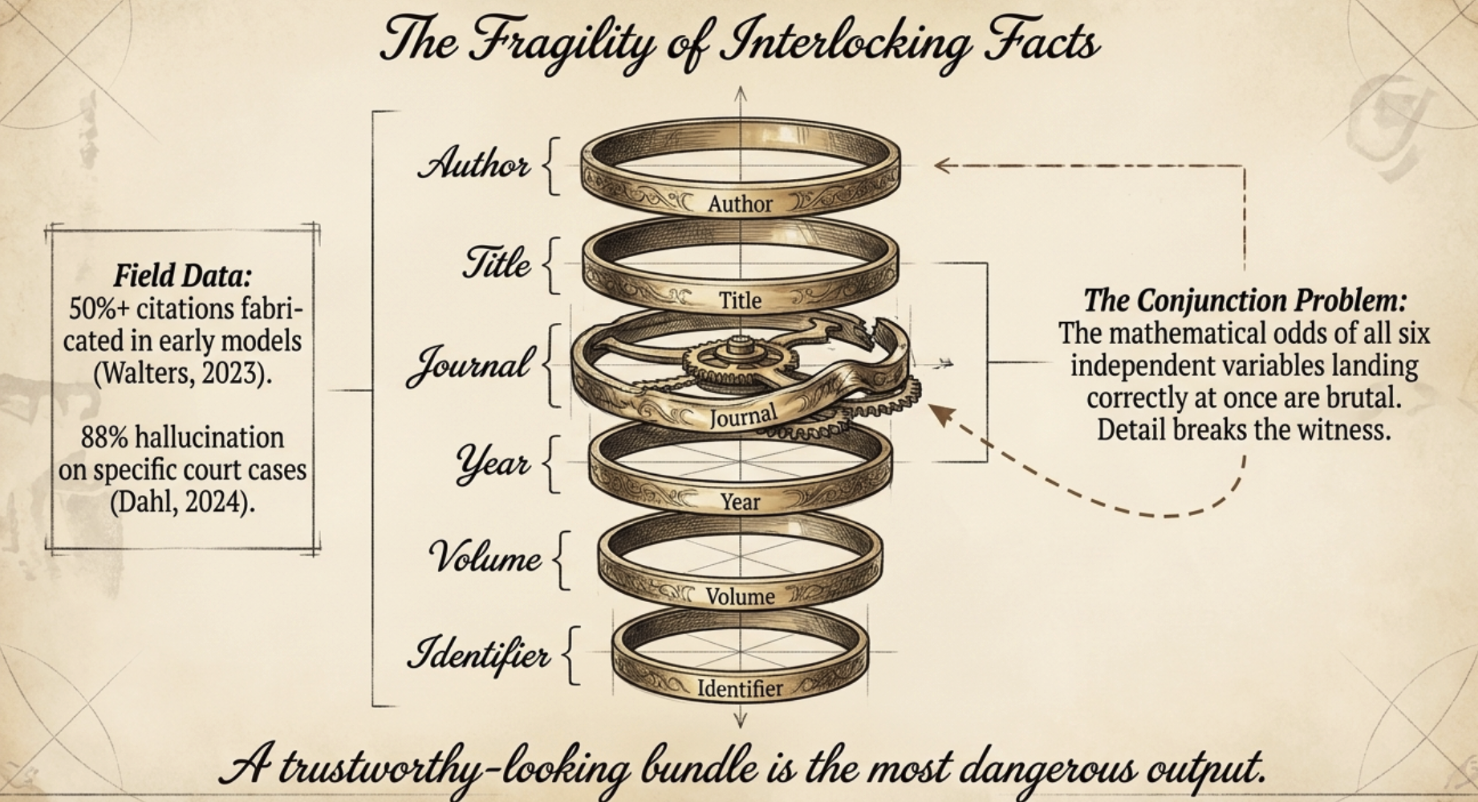
A citation isn't one fact but a conjunction of facts: author, title, journal, year, volume,
identifier. Even if the model has a decent chance of getting each field right independently, the
chance of getting the entire bundle right falls quickly. It's the same reason detailed eyewitness
testimony becomes fragile as you ask for more specifics.
10. Can a different architecture fix this?
Not fully, not with what we have today, and not with anything credibly close, either.
There's genuine disagreement. One camp, including the researchers behind that hallucination
paper, argues it isn't strictly unavoidable, since a model can always abstain, and the fix is mostly
training and scoring, not architecture [1]. Another camp argues it's a deeper, structural limit of
11/20how current transformers work [18]. My reading: both are pointing at real things. Some errors
are baked into learning from text at all. But whether they show up as confident, undetected
falsehoods or as flagged, honest uncertainty is a choice we make in training. The first part may
be structural. The second isn't.
Grounding represents today's most viable pragmatic solution.
Grounding is the practical answer available today. Put the relevant document in context and
the model no longer has to reconstruct a rare fact from a lossy internal representation; it can
read it from the page [21]. It's the difference between recalling a colleague's employee ID from
memory and reading it from the directory.
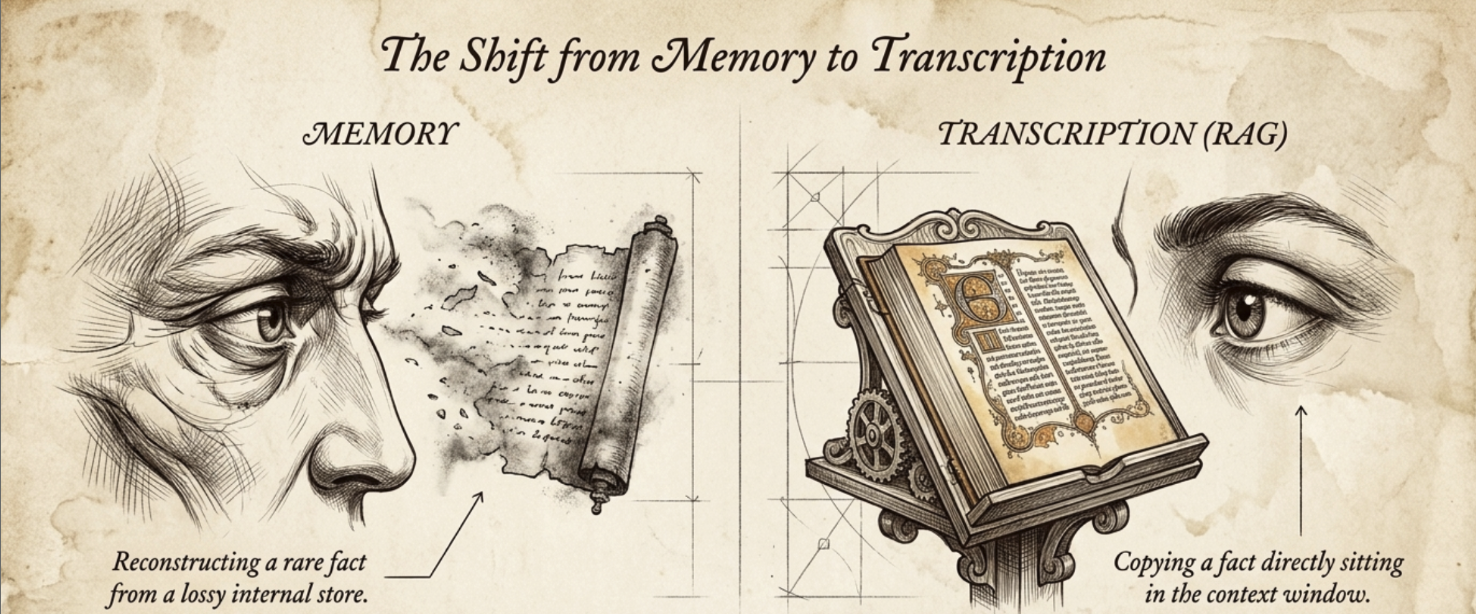
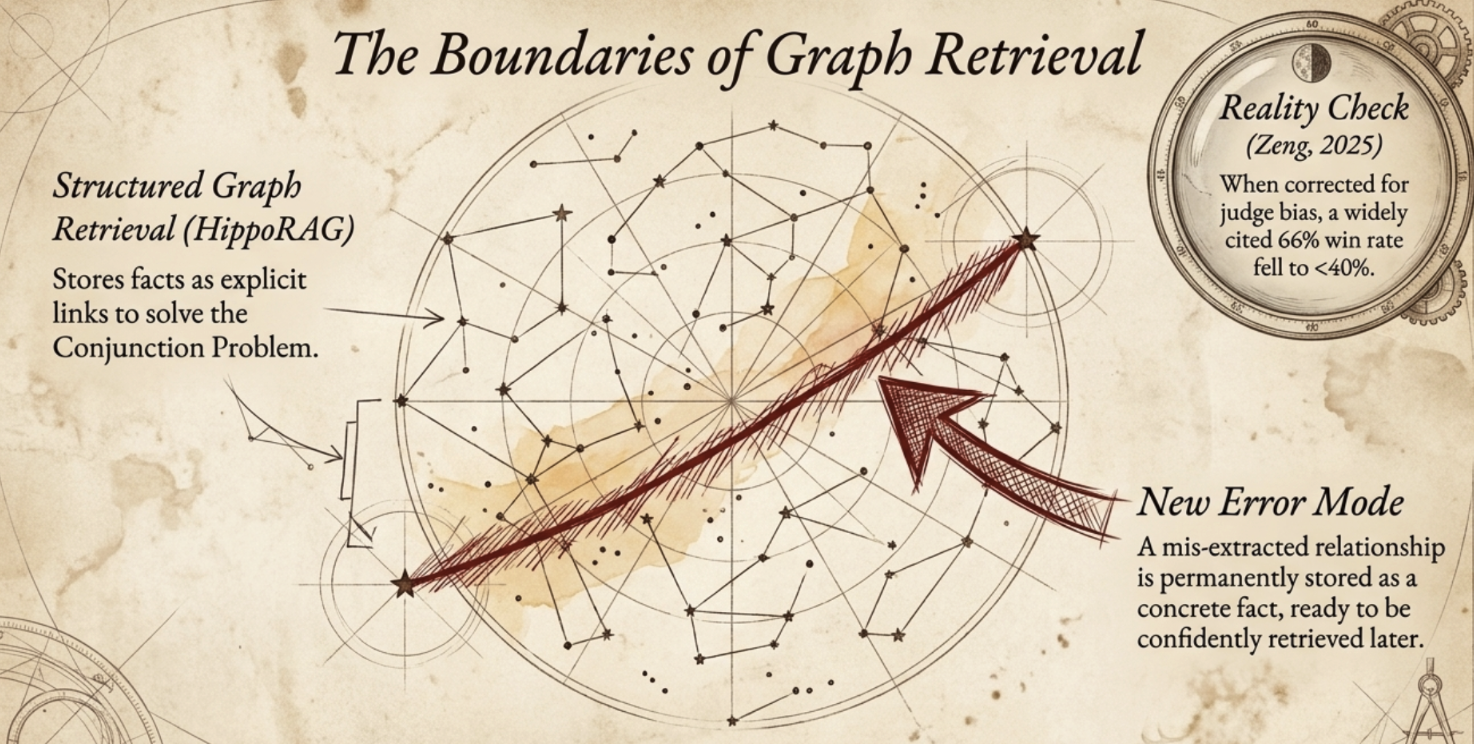
Graph-based retrieval goes one step further by explicitly storing relationships between
facts, which can help when an answer requires chaining several of them [22]. But the gains are
narrower than the marketing suggests: corrected evaluations have substantially reduced some
reported advantages [23], and a wrongly extracted relationship simply creates a new confidently
retrievable error.
We ended up testing a version of this idea at Parser, first as an internal proof of concept
and later as something we could reuse with customers. We built a helper over a large body
of internal information, but instead of treating every question the same way, it decides how
much grounding the answer needs. It can answer directly when the information is already
reliable in context, use conventional retrieval (RAG) for simpler facts, move to GraphRAG
when the question depends on relationships between facts, or call an external tool such as
web search when the evidence isn't available internally. It can run that search-and-check
loop up to three times before giving up. The important part isn't the particular stack; it's the
last rule: if it still can't point to evidence for the answer, it should decline rather than fill the
gap with something plausible.
For context, we built that implementation with LangChain and LangSmith, Qdrant for vector
retrieval, Neo4j for the graph, and reasoning models orchestrating the search agent and
verification steps.
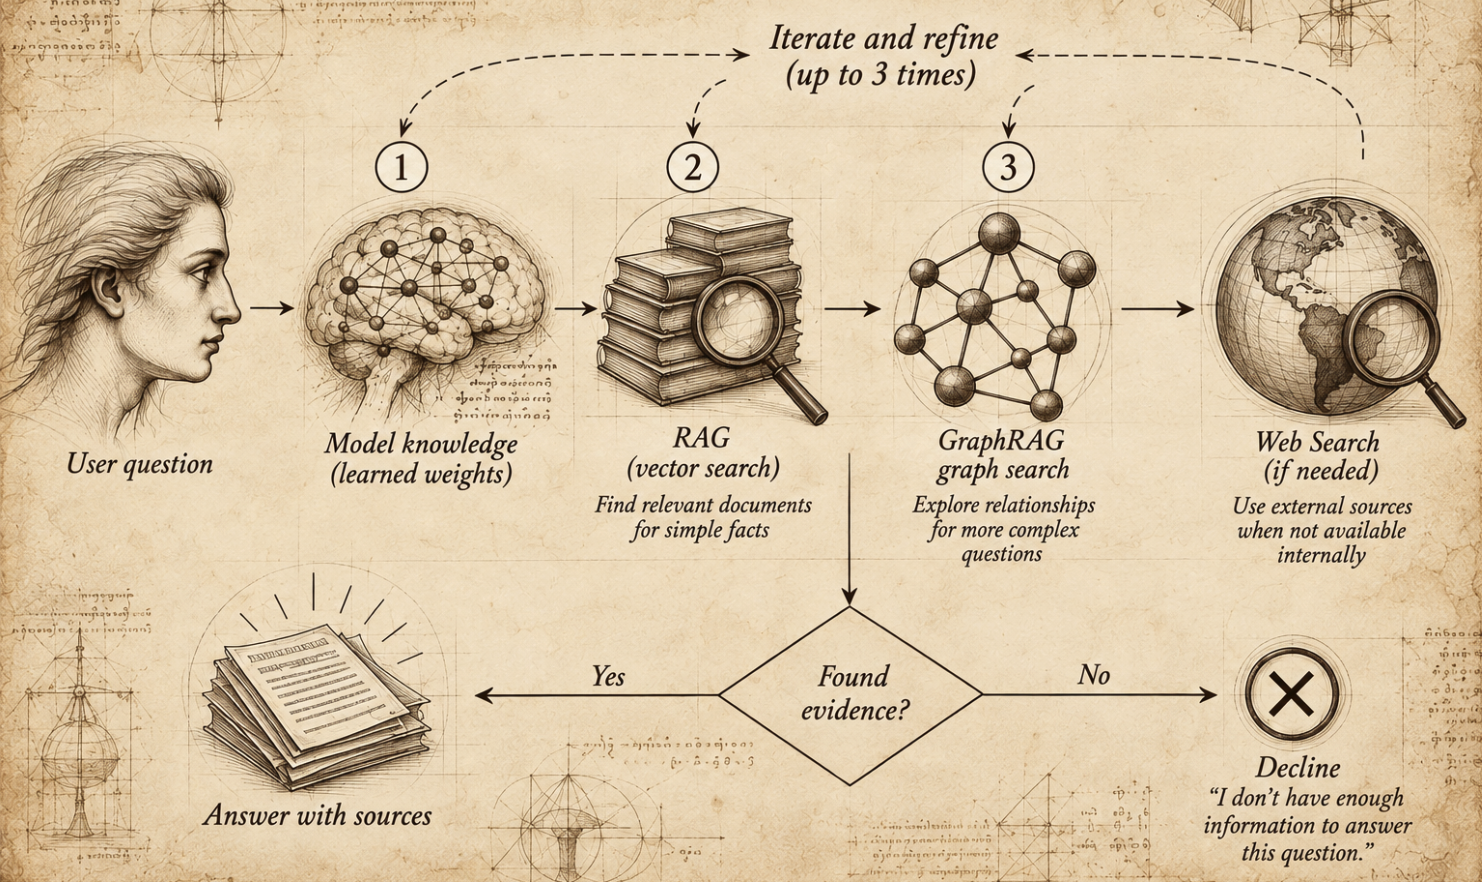
A simplified view of the agentic grounding approach we experimented with at Parser. The objective is
not to make the model “know more,” but to force increasingly explicit evidence before it answers.
None of it cures the disease. It changes the task, and makes an unsupported answer
progressively harder to produce. But the last line of defence still matters: when retrieval, graph
traversal and external tools all come back empty, the model has to be allowed to say so.
With the right document in front of it, the model is no longer being asked to remember.
It's being asked to read. That's much easier, but still not infallible.
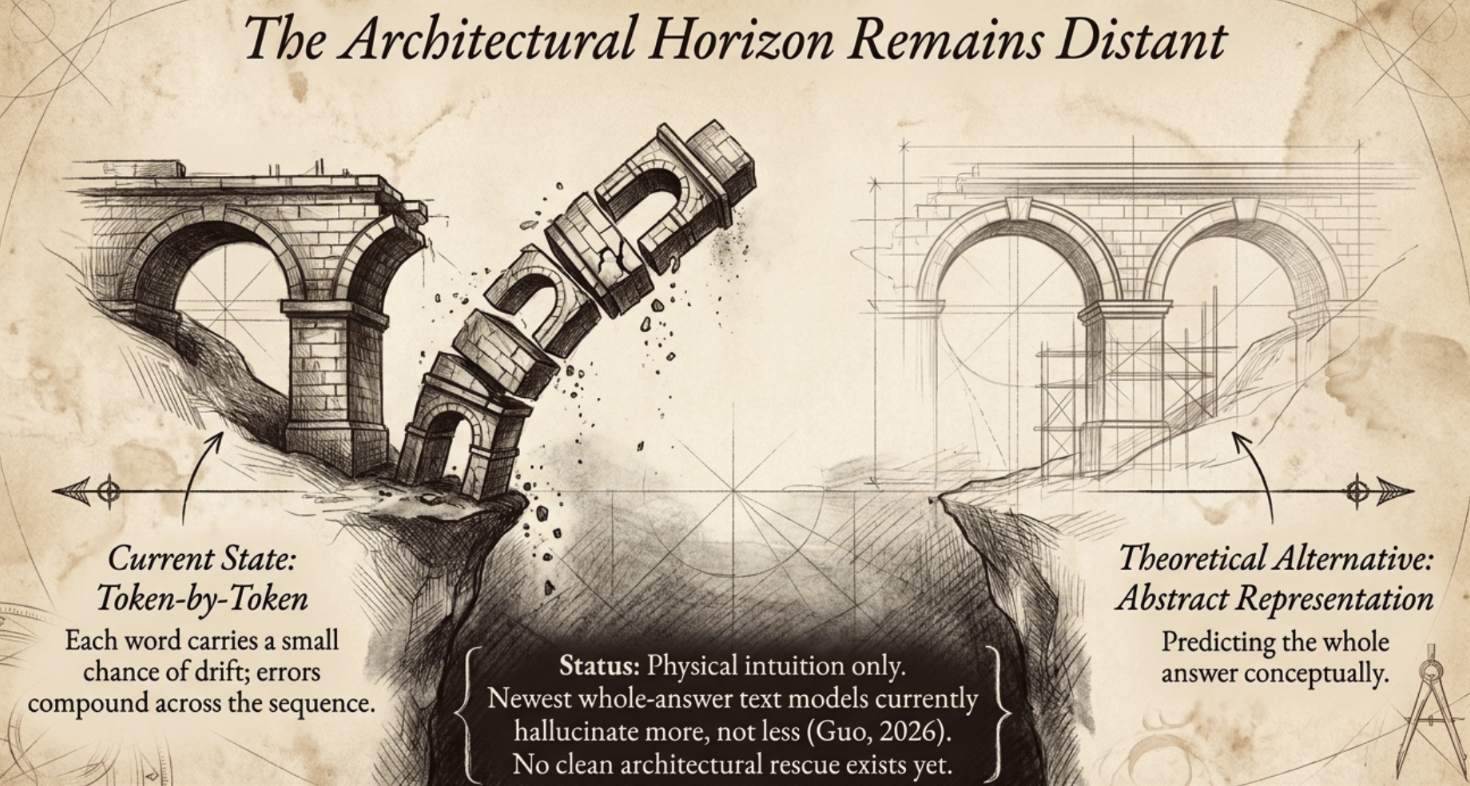
As for a genuinely different architecture: Yann LeCun has argued predicting one word at a
time is inherently fragile, each token carries a small chance of drift, and those chances
compound across a response [24]. His proposed alternative predicts in an abstract
representation rather than word by word, and has produced strong results, but only in a
different domain, teaching a model physical intuition from video. To date, I haven’t seen any
functional implementation of this capable of addressing written factual queries, leaving the
approach unbenchmarked and positioned as an active research vector rather than a viable
alternative. I found one controlled comparable alternative, a whole-answer-at-once model
against a matched word-by-word one. Resulting that the newer architecture hallucinated
more, not less [25].
I went in hoping for a clean architectural rescue. I came out with a document directory, a
promising map for a narrow class of questions, and one interesting bet still years from paying
off. »
11. What I'd actually put in place today
First, ground it. Give the model real source documents and require it to answer from them, or
abstain. Measure two numbers separately: how often it's wrong and how often it says “I don't
know.
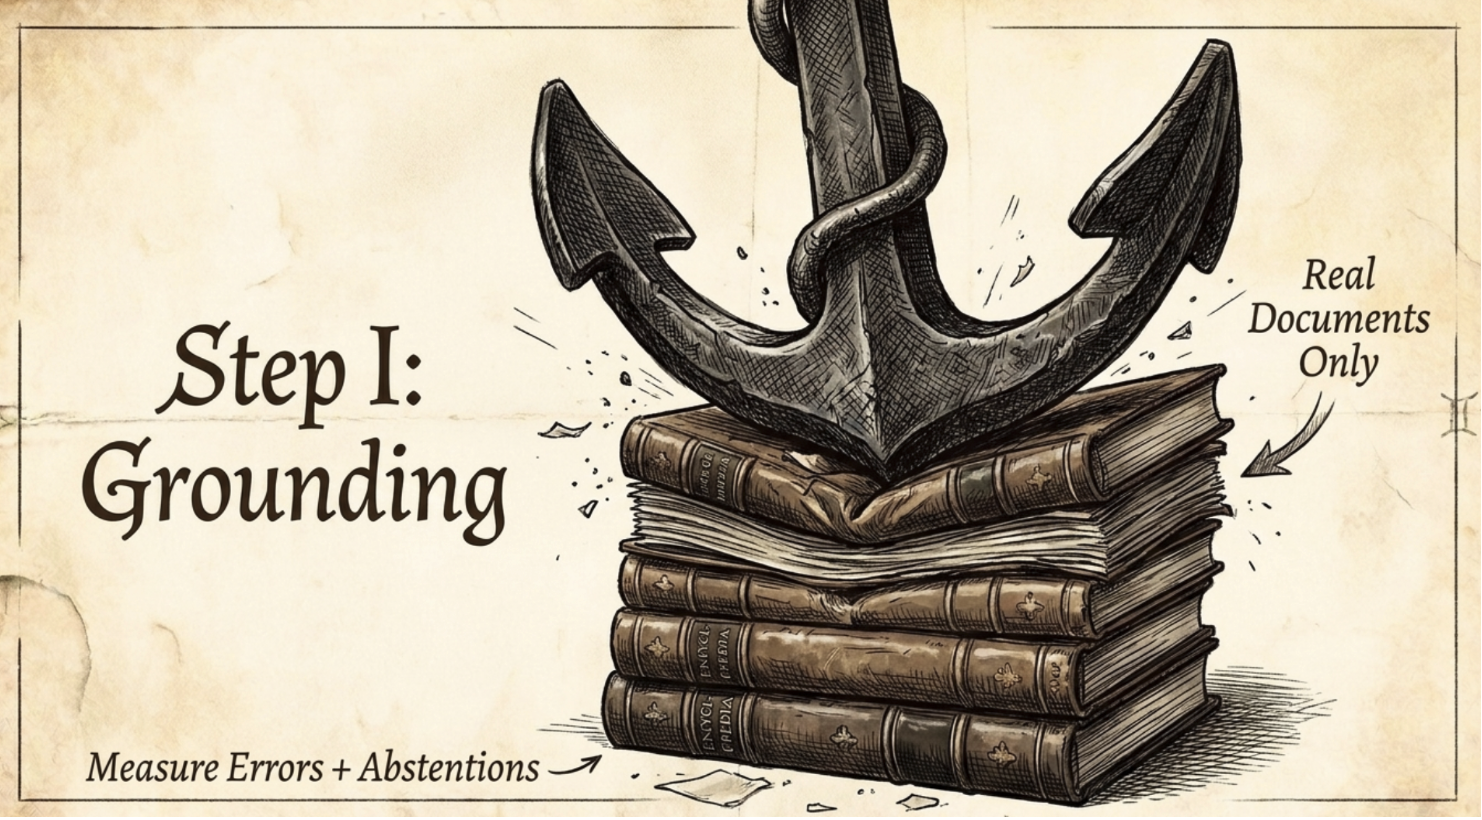
” Collapsing those into a single accuracy score recreates the incentive problem that got us
here. A study of commercial legal research tools, built specifically with retrieval to fix this, still
found hallucination rates between 17% and 33% [20].
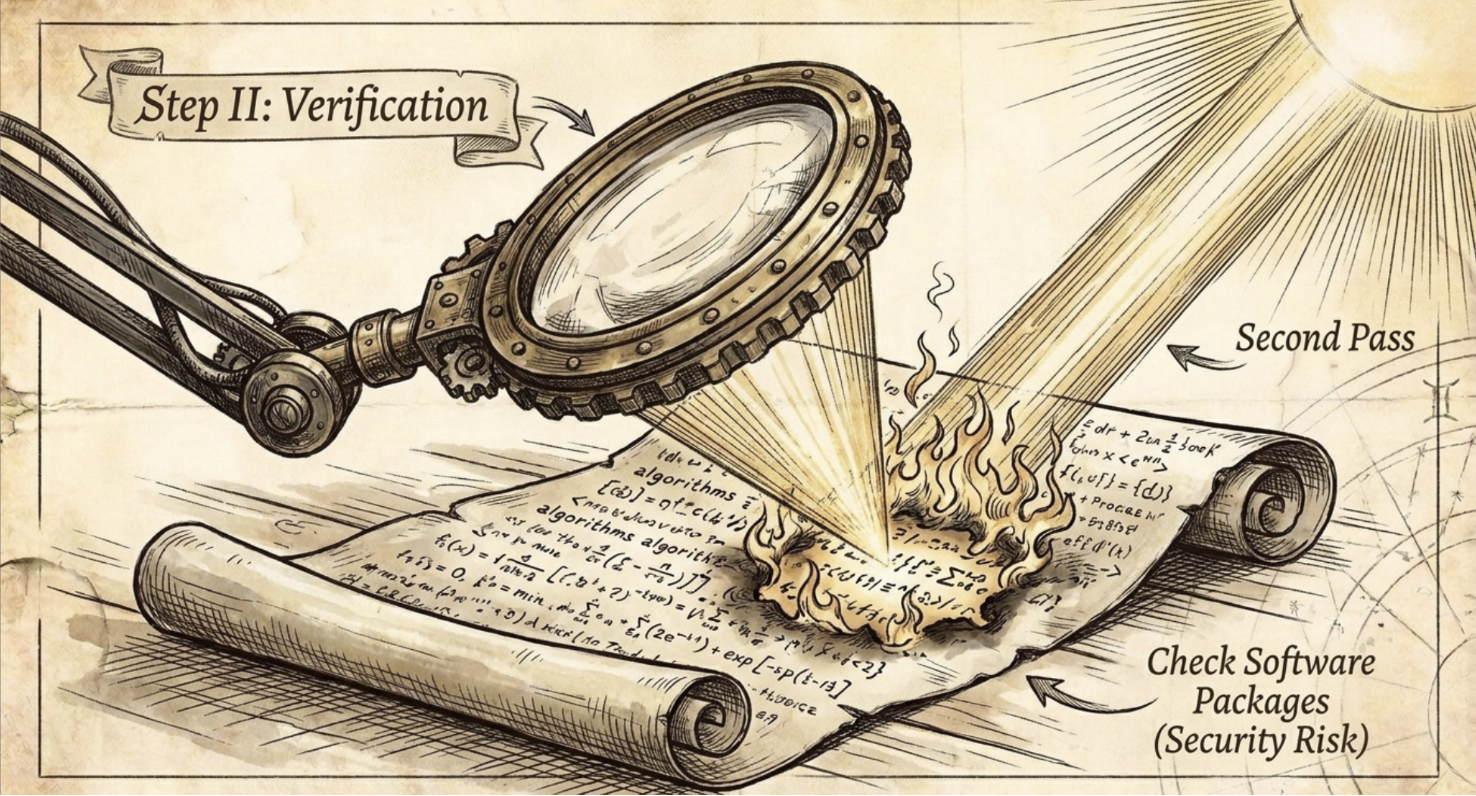
Second, verify before trusting. For long-form or high-stakes outputs, check factual claims
against real sources before they reach the user. For code, verify that every referenced package
actually exists.
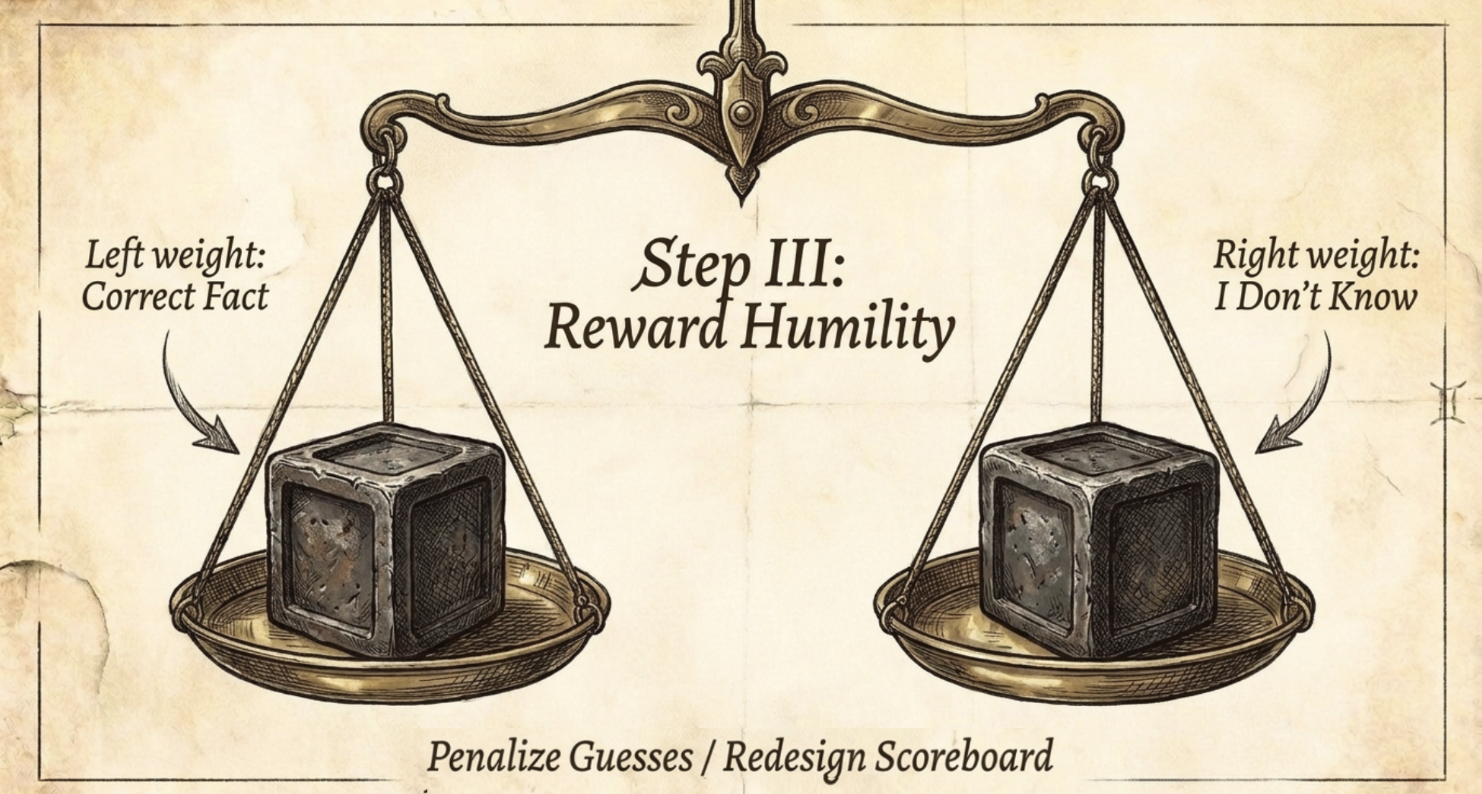
Third, reward abstention. If you're training or fine-tuning models, treat “I'm not sure” as a valid
outcome rather than a failure [19]. Confidence without knowledge is exactly the behaviour you're
trying to remove.
And before building a product around a model's internal knowledge, ask one question: how
often did this kind of fact plausibly appear in training? If the answer is “rarely,
” you don't
have a prompting problem. You have a retrieval problem.
All the limitations described earlier are real, but they shouldn’t stop anyone deploying these
models. I think they should stop anyone deploying them without measuring the gap.
12. The light at the end of the tunnel
So I no longer think “hallucination” is merely a polite word for lying. Lying requires knowing the
truth and choosing otherwise; an ordinary error implies the system failed while trying to retrieve
it. What we're seeing is closer to a confident guess from a system never taught a clean
distinction between knowing and guessing, and often rewarded by us for guessing anyway.
Juniors guess because a blank answer feels like incompetence. Seniors say “let me check”
because they've learned what a wrong answer costs later.
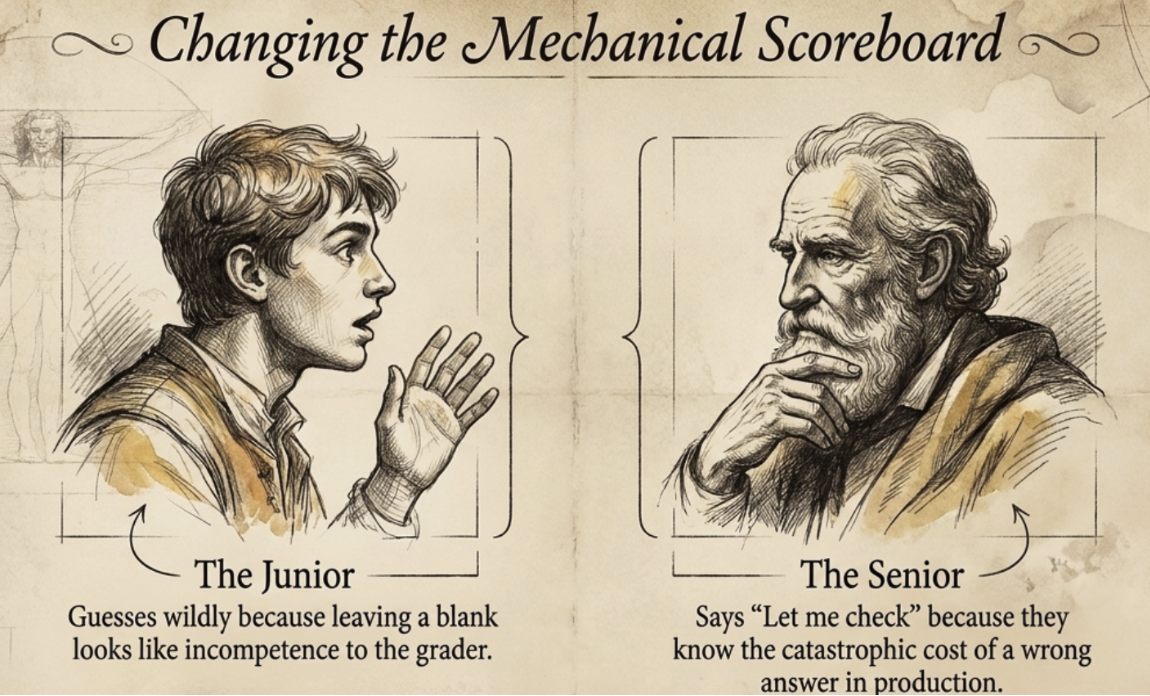
Our models are still juniors, not because they're small or incapable, but because we
built them a scoreboard where a blank answer scores zero, then acted surprised when
they stopped leaving blanks.
That part, at least, is entirely within our control to change.
A note from the author
This article is part of a broader journey I've been following as an engineer and CTO: trying to
understand new technologies beyond the headlines, then testing what that understanding
means in practice. At Parser, many of those questions become experiments and eventually
working systems: from agentic software engineering to assistants grounded through RAG,
GraphRAG and external tools. Writing about them is another way of forcing myself to
understand not only what these technologies can do, but where their limits really are.
References
[1] Kalai, A. T., Nachum, O., Vempala, S., Zhang, E.
"Why Language Models Hallucinate"
.
OpenAI, September 2025. https://arxiv.org/abs/2509.04664. It was updated and published in
Nature in April 2026 under "Evaluating large language models for accuracy incentivizes
hallucinations" vol. 653, pp. 1047–1051. https://www.nature.com/articles/s41586-026-10549-w
[2] Anthropic.
"Tracing the Thoughts of a Large Language Model"
, Claude 3.5 Haiku, March
2025. https://www.anthropic.com/research/tracing-thoughts-language-model
[3] Kandpal, N. et al.
"Large Language Models Struggle to Learn Long-Tail Knowledge.
"
ICML 2023. https://arxiv.org/pdf/2211.08411
[4] Allen-Zhu, Z., Li, Y.
"Physics of Language Models: Part 3.1, Knowledge Storage and
Extraction.
" 2024. https://dl.acm.org/doi/10.5555/3692070.3692115
[5] Lee, N., Ping, W., et al.
"Factuality Enhanced Language Models for Open-Ended Text
Generation"
. NeurIPS 2022. https://arxiv.org/pdf/2206.04624v3
[6] Renze, M., Guven, E.
"The Effect of Sampling Temperature on Problem Solving in Large
Language Models"
. 2024. https://arxiv.org/abs/2402.05201
[7] Manakul, P., Liusie, A., Gales, M.
"SelfCheckGPT"
. EMNLP 2023.
https://arxiv.org/abs/2303.08896
[8] OpenAI.
"o3 and o4-mini System Card"
. April 2025. https://cdn.openai.com/pdf/
2221c875-02dc-4789-800b-e7758f3722c1/o3-and-o4-mini-system-card.pdf
[9] OpenAI.
"GPT-5 System Card"
. August 2025. https://arxiv.org/abs/2601.03267
[10] "EDT: Entropy-based Dynamic Temperature Sampling"
, and the entropix project.
https://github.com/xjdr-alt/entropix
[11] Asai, A. et al.
"Self-RAG"
. 2024; https://arxiv.org/abs/2310.11511
Jiang, Z. et al.
"FLARE.
" 2023. https://arxiv.org/abs/2305.06983
[12] Mallen, A., Asai, A. et al.
"When Not to Trust Language Models"
. ACL 2023.
https://arxiv.org/abs/2212.10511
[13] Anthropic.
https://arxiv.org/abs/2505.05410
[14] Walters, W. H., Wilder, E. I.
"Fabrication and errors in ChatGPT-generated bibliographic
citations"
. Scientific Reports, 2023. https://www.nature.com/articles/s41598-023-41032-5
[15] Dahl, M. et al.
"Large Legal Fictions"
. Journal of Legal Analysis, 2024.
https://arxiv.org/pdf/2401.01301
[16] Mata v. Avianca, Inc., S.D.N.Y., June 2023.
https://www.jdsupra.com/legalnews/federal-court-turns-up-the-heat-on-1849454/
[17] Spracklen, J. et al.
"We Have a Package for You!" USENIX Security 2025.
https://www.usenix.org/system/files/usenixsecurity25-spracklen.pdf
[18] Xu, Z. et al.
"Hallucination is Inevitable"
. 2024. https://arxiv.org/abs/2401.11817
"Reasoning Models Don't Always Say What They Think"
, 2025.
19/20[19] Lin, S. et al.
"FLAME"
. NeurIPS 2024. https://arxiv.org/abs/2405.01525
[20] Magesh, V. et al.
"Hallucination-Free? Leading AI Legal Research Tools"
. Stanford
RegLab, 2024. https://reglab.stanford.edu/publications/hallucination-free-assessing-
the-reliability-of-leading-ai-legal-research-tools/
[21] Olsson, C. et al.
"In-Context Learning and Induction Heads"
. Anthropic, 2022;
https://arxiv.org/abs/2209.11895
Lewis, P. et al.
"RAG.
" 2020. https://proceedings.neurips.cc/paper/2020/hash/
6b493230205f780e1bc26945df7481e5-Abstract.html
[22] Gutiérrez, B. et al.
"HippoRAG"
. NeurIPS 2024. https://arxiv.org/abs/2405.14831
[23] Zeng, Q. et al.
"Unbiased Evaluation Framework for GraphRAG"
, 2025.
https://arxiv.org/html/2506.06331v2
[24] (PODCAST) LeCun, Y. Lex Fridman Podcast #416, March 2024.
https://lexfridman.com/yann-lecun-3/
[25] Guo, Y. et al.
"Lost in Diffusion"
, 2026. https://arxiv.org/html/2604.10556v1
[26] (VIDEO) Stanford CS229 I Machine Learning I Building Large Language Models (LLMs),
Yann Dubois, Summer 2024.